The real price of AI document processing
The price of an AI model isn’t the price of an enterprise extraction solution.
While open-source or open-weight models may be free to download, turning unorganized business documents like multi-page PDFs, scans, invoices, contracts, and spreadsheets into governed, high-precision structured data is a complex engineering challenge. A raw model weight alone can’t parse tables, handle skewed scans, isolate specific key-value pairs, or route extracted data directly into enterprise workflows.
To build a self-hosted document processing pipeline, organizations must deploy and manage GPUs, optical character recognition (OCR) engines, layout-aware parsers, vector/search retrieval pipelines, orchestration layers, security guardrails, and ongoing MLOps tooling.
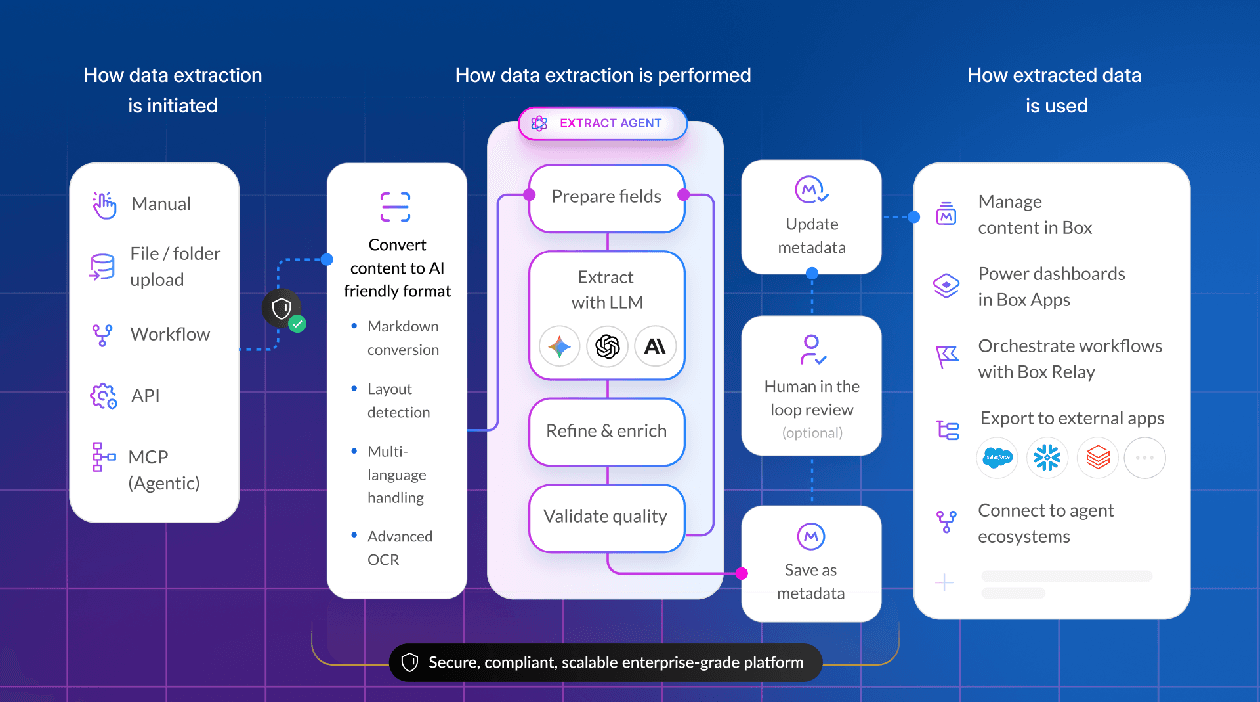
For most enterprises, Box Extract delivers a significantly lower total cost of ownership (TCO). By providing advanced extraction capabilities as a fully managed, native service directly within Box’s Intelligent Content Management (ICM) platform, Box Extract eliminates infrastructure overhead, slashes time-to-value, and automatically populates extracted metadata where your content already lives.

The "free model" trap: what DIY actually costs
Industry analyses of LLM economics consistently show that model licensing represents only a fraction of total solution cost. When building an in-house extraction service, IT leaders must budget for the full operational ecosystem over a multi-year horizon:
- Compute & accelerator overhead: Procuring or reserving dedicated high-memory GPUs (e.g., A100/H100 instances), networking, power, and rack space.
- Peak capacity vs. idle waste: Self-hosted services must be provisioned for peak batch processing and tight SLA windows, meaning costly GPU clusters sit idle during off-peak periods.
- Document ingestion & multi-modal pipelines: Pre-processing complex business files requires dedicated file conversion, robust OCR for degraded scans, layout-aware chunking, and tabular structure extraction before a model is even called.
- MLOps & infrastructure maintenance: Ongoing engineering labor is necessary for driver compatibility, serving framework optimization (e.g., vLLM, TensorRT-LLM), latency monitoring, failover handling, and security patching.
- Security, governance & access controls: In-house pipelines require custom-built role-based access control (RBAC), audit logging, data residency compliance, and secure data retention policies to prevent leaks.
- Downstream integration friction: Custom extractors need bespoke connectors to pipe output into downstream databases, line-of-business applications, and search indexes.
Box Extract: Purpose-built extraction native to your content
[ Raw Documents: Scans, PDFs, Office Files, Images ]
                     │
                     ▼
┌────────────────────────────────────────────────────────┐
│                     BOX EXTRACT                        │
│  • Built-in OCR & Layout Understanding                 │
│  • Specialized Extract Agents (Standard & Enhanced)    │
│  • Field-Level Prompt Instructions & Validations       │
└────────────────────────────────────────────────────────┘
                     │
                     ▼
[ Governed Box Metadata ➔ Search, Automations, Workflows, APIs ]
Box Extract replaces the fragmented DIY stack with an integrated, intelligent extraction engine designed specifically for enterprise content.
- Dual Extract agent architectures:
- Standard Extract agent: Optimized for cost-effective, high-throughput extraction across high-volume structured and semi-structured documents (e.g., standard receipts, POs, standardized forms).
- Enhanced Extract agent: Leverages frontier reasoning models and extraction-specific contextual retrieval for complex, unstructured, or dense multi-page documents (e.g., nuanced commercial agreements, regulatory filings, medical records).
- No-code configuration & field-level prompting: Business process owners can define custom schema fields, data types, and natural language field-level instructions without writing code or filing engineering tickets.
- Seamless metadata automation: Extracted values are directly written as structured Box Metadata instances on the source file. This instantly empowers Box Automate workflows, granular metadata search, Box Governance retention policies, and downstream ecosystem integrations (via Box APIs, Salesforce, ServiceNow, SAP, etc.).
- Zero ingestion/egress friction: Documents don’t need to be exported to third-party vector databases or staging buckets; processing happens securely within Box's trusted security perimeter.
Side-by-Side: DIY Open-Weight Architecture vs. Box Extract
Capability Area | Self-Hosted Open-Weight Pipeline | Box Extract (Managed Service) |
Infrastructure & Compute | Procure/reserve dedicated GPUs; pay for idle headroom and redundancy. | Fully managed serverless capacity; pay for what you extract with zero idle hardware costs. |
Document Processing Pipeline | Stitch together OCR libraries, layout parsers, chunkers, and file converters. | Native, end-to-end multi-modal document pipeline with state-of-the-art OCR and layout parsing. |
Model Evolution & Upgrades | Continuously benchmark, re-prompt, re-test, and migrate across new open releases. | Seamless continuous upgrades to frontier models and extraction algorithms without breaking changes. |
Security & Compliance | Build custom RBAC, zero-trust perimeter, audit logs, and compliance attestations. | Inherits Box enterprise-grade security, HIPAA/SOC/ISO compliance, and strict data privacy. |
Enterprise Integration | Build and maintain custom APIs to push data to databases and business systems. | Automatic assignment to Box Metadata; out-of-the-box integration with Box Automate, Hubs, and APIs. |
Accuracy drives the true ROI
The most economical extraction solution isn’t the one with the cheapest raw compute cost; it’s the one that delivers accurate, trustworthy data with the lowest human review and remediation overhead.
Extracting data from complex business documents requires handling degraded scans, complex tables, multi-column layouts, and fine print. Even small differences in field-level accuracy yield massive operational cost differences at scale.
The Compounding Cost of Errors (Monthly 100,000 Field Workflow)
Monthly Field Volume | Accuracy Rate | Expected Error Count | Operational Impact |
100,000 fields | 98.0% | 2,000 errors | High manual review, frequent workflow bottlenecks |
100,000 fields | 99.0% | 1,000 errors | 50% fewer errors to review and remediate |
100,000 fields | 99.9% | 100 errors | 90% reduction in remaining errors vs. 99.0% |
Note: Every avoided error eliminates costly human-in-the-loop exception handling, reprocessing cycles, and the business risk of downstream decision errors.
With Box Extract's field-level instructions, extraction-specific retrieval, and reasoning capabilities, teams achieve higher baseline accuracy out of the box, drastically cutting operational rework.
When does self-hosting make sense?
Building a custom in-house extraction stack may be appropriate for organizations that:
- Already maintain a mature, dedicated MLOps and GPU cluster operating at constant 85%+ utilization.
- Require deep, custom fine-tuning of domain-specific model weights.
- Operate under isolated, air-gapped data sovereignty mandates where external cloud services can’t be used.
But for organizations looking to quickly unlock structured data from contracts, financial records, HR files, and operational documents where Box is already the primary content repository, building custom duplicate infrastructure creates unnecessary technical debt and ongoing operational risk.
Conclusion: Focus on outcomes, not infrastructure
A modern AI strategy should focus engineering resources on core business differentiation, not on operating document conversion servers and GPU clusters.
By uniting enterprise-grade LLMs, purpose-built extraction agents, and seamless metadata integration directly within your governed content layer, Box Extract delivers faster deployment, lower operational risk, and superior total cost of ownership.
Ready to see what Box Extract can do with your documents? Contact your Box account team to explore live demos, evaluate schema configurations, and model your workload ROI.